A decade ago, talking about data at a college meant talking about the future. Today it means talking about operations. Nearly one in four students who start college in the United States never comes back for a second year, and the institutions that catch that pattern early are the ones running on data. That is where big data in higher education stopped being a roadmap item and became part of the enrollment plan.
The National Student Clearinghouse Research Center reports that 76.5% of students who started in fall 2022 persisted into a second year, and that only 68.2% returned to the same institution. Both figures are ten-year highs, which makes the remaining gap the most expensive line in many enrollment budgets.
Most institutions do not suffer from a shortage of data. They suffer from data scattered across systems with no owner and no reading. The student information system knows who missed class, the CRM knows who requested information, the learning platform knows who stopped logging in, and none of the three talks to the others.
We must also not forget that Big Data plays a strong role in university marketing, because we need to know the profile of our ideal student, find them long before the entrance exam and prepare them for their higher education journey.
What is big data in higher education and what changed?
Big data in higher education is the practice of gathering high volumes of data from different sources, academic, behavioral, financial and marketing, to answer questions a single spreadsheet cannot. What changed over the past decade is not the concept. It is the cost of execution and the level of automation available off the shelf.
Ten years ago, building that foundation required an infrastructure project, an expensive license and an in-house team. The bottleneck has since flipped: storing and processing became cheap, interpreting and acting became the hard part.
Educational institutions are major producers of information. From capturing leads to the academic management of students, your team's work input is certainly knowledge.
Student demographics, the marketing channels used to attract students, interactions at each point of contact, enrollment control, the profile of graduates, difficulties encountered during the course of the degree - all this is information that can be transformed into a competitive advantage for your Educational Institution.
The role of Big Data is to collect this data from various sources, compare it in real time and extract insights that help with strategic planning, marketing strategies, choosing the courses to offer, putting together curricula and monitoring students, offering teaching that is increasingly personalized and aligned with the expectations of students and, of course, the job market in which they find themselves.
Three shifts explain the difference. The first is prediction becoming routine. Machine learning models now ship inside CRM, student information and business intelligence products, often without anyone writing code.
The second is generative AI as a reading layer. A language model does not replace an analyst, but it summarizes patterns and answers plain-language questions about a dashboard, which shortens the distance between data and decision.
The third is governance moving from footnote to requirement. With privacy regulation enforced across major markets and first-party data becoming a media asset, how you collect now determines what you are allowed to do later. Even the tool vocabulary is worth checking: Google's free dashboarding platform launched as Data Studio, was rebranded Looker Studio, and went back to Data Studio in the official documentation.
In short, when we talk about Big Data, we are referring to a set of technologies that favor decision-making, identifying opportunities where the human eye cannot reach.
These technologies already permeate the educational environment, such as ERP, CRM, marketing automation software, virtual learning environments, among others. Put together, they help your Educational Institution become better every day.
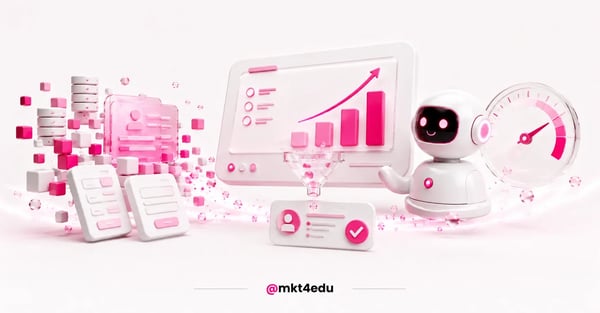
Subtitle: Big data in higher education starts with scattered records and ends in a decision: who is at risk of dropping out and which channel enrolls.
Why is big data in higher education a priority right now?
Because the math of higher education changed. Enrollment is more volatile, delivery is more digital, and completion remains the weak point, which makes data the only realistic way to run a larger and more dispersed student base with any predictability.
The completion numbers frame the stakes. According to the National Center for Education Statistics, the six-year graduation rate for students who began at four-year institutions in fall 2014 was 64% overall, ranging from 68% at private nonprofit institutions to 29% at for-profit ones. Every student recruited with media spend, staff time and financial aid who leaves before completing returns only a fraction of the projected value.
Sector leaders already treat this as a governance issue. The 2026 EDUCAUSE Top 10, the annual ranking of technology priorities in higher education, places four data themes among the ten most pressing: analytics for operational and financial insight, building a data-centric culture, moving from reactive to proactive forecasting and data literacy among decision makers.
That last item is the uncomfortable one. Having the dashboard is not enough. Someone with authority has to be able to read it.
Gartner reported in April 2026 that organizations with successful AI initiatives invest up to four times more, as a percentage of revenue, in data and analytics foundations such as data quality, governance and change management. In the same survey of 353 data and AI leaders, only 39% were confident that current AI investments would produce positive financial impact.
Which data does your institution already have for analytics?
Almost every institution already generates enough data for a first analytics cycle. What is usually missing is inventory and integration, not new collection. Before buying any platform, map what exists, who owns each dataset and how often it is updated.
Five sources cover most of the early value. Here is how they organize:
| Source | What it records | Question it starts answering |
|---|---|---|
| Recruitment CRM | lead source, interactions, applications | Which channel brings prospects who actually enroll? |
| Student records and ERP | grades, attendance, financial standing | Who is accumulating risk signals this term? |
| Learning management system | logins, submissions, inactivity | Who stopped showing up before they stopped paying? |
| Website, analytics and paid media | pageviews, form fills, cost per lead | Which programs generate demand nobody serves? |
| Service desk and messaging | questions, complaints, abandoned chats | Where do applicants drop out mid-process? |
Tabela: Each row is a dataset most institutions already maintain, in systems that rarely speak to one another.
Cross-referencing just two of those sources usually produces the first meaningful insight. Connecting paid media to confirmed enrollment separates channels that generate volume from channels that generate students.
One methodological caution is worth carrying. A systematic review published in Education and Information Technologies, covering 75 studies on big data and analytics in higher education between 2011 and 2022, notes that, in part of the studies reviewed, the scope tends to ignore variables outside the learning platform.
Platform engagement is a strong signal, but it rarely explains on its own why a student leaves: finances, commuting and work schedules still matter, and part of that only surfaces in a conversation logged by the service desk.
How do you use recruitment data without third-party cookies?
The short answer is to build recruitment on first-party data, collected with consent and organized in the CRM. Cross-site tracking became less reliable, which raised the value of everything an institution records in channels it controls.
Google's plan to replace third-party cookies in Chrome did not unfold as announced, and the initiative's own official page states that some Privacy Sandbox technologies are being phased out. Neither the old tracking works well nor the replacement consolidated.
For an institution, that means three concrete adjustments.
The first is treating forms and service interactions as a primary data source. Every field you request needs a defined use, because unused fields only cost conversion.
The second is connecting media spend to outcomes inside the CRM, not only inside the ad platform. When lead source travels with the person all the way to enrollment, the discussion about whether Performance Max is worth it stops being about cost per click and becomes about cost per enrolled student.
The third is using data to decide who gets human attention first. Scoring models combine on-site behavior, program of interest and interaction history to order the queue. This is where AI-powered lead qualification pays off quickly, and where formats like the interactive funnel help, because the prospect's own navigation reveals interest and readiness.
The sensitive part is base quality. In HubSpot's State of Marketing 2026, surveying more than 1,500 marketers, only 65% said they have high-quality audience data. Dirty data does not improve because you bought a new tool.
Platforms such as HubSpot, Google Analytics 4 and IBM's watsonx line already ship predictive analytics features, which lowers the need for a custom project. Check the naming before you standardize internal documentation: IBM now presents Watson as the earlier stage and watsonx as its current line of AI and data products.
How does big data personalize the learning experience?
One of the great challenges for higher education institutions is to respect the peculiarities of each student and offer personalized teaching that helps build new skills and improve existing ones, without losing sight of the market's demands regarding the professional profile that graduates must present.
In this sense, Big Data is today the greatest ally of Educational Institution. By analyzing each student's historical data, which can be tracked since childhood, it is possible to determine each student's greatest difficulties and create personalized curricula.
Technology courses, for example, have a lot to gain from this. With data analysis, each Educational Institution can assess the social and economic context of its region and tailor technology degree courses to local needs, generating value for the population and contributing to the country's social and economic development.
The students' unique experience is also transformed into word-of-mouth advertising, visibility on social networks and a reason to stand out for the Educational Institution, which ends up with a stronger reputation for using technological resources to offer quality teaching.
This is where data helps in very concrete ways. With performance history, login patterns and submission records, an institution can see where a cohort stalls, which content needs reinforcement and which students would benefit from a different pathway.
Personalization has a limit, and it deserves to be stated. Platform data shows behavior, not motive. A student who stopped logging in may be lost in the material, out of time because of work or in financial difficulty, and only a conversation reveals which of the three it is.
How does predictive analytics anticipate student dropout?
Predictive analytics anticipates student dropout by learning, from historical records, which behavior combinations precede leaving, then applying that pattern to current students. The goal is not to be right about the future. It is to buy weeks of lead time while the departure is still reversible.
The scale of the problem is easy to underestimate. In the United States, only 68.2% of students who started in fall 2022 returned to the same institution for a second year, and that figure is a ten-year high.
The reasons for dropping out are many: from a lack of resources to continue paying for studies, to a lack of identification with the chosen career.
Recent research is encouraging. A study published in Scientific Reports, applying machine learning to Moodle access logs across 23 courses, reached 0.90 accuracy and 0.95 AUC in predicting dropout, with performance measured week by week: by week 7 the model recorded 0.95 AUC and 0.86 F1. In practice, behavior from the early weeks is already enough for a useful model, without waiting for the end of the term.
The most predictive signals in that model say a lot about where to look: regularity of access, the longest consecutive stretch without logging in and total course duration. It is not the failing grade that shows up first. It is the silence.
Students who have not undergone a vocational orientation process or who have been pressured by their family to follow a certain career path are also strong candidates for dropping out.
Acting proactively in these cases can prevent an increase in the dropout rate and build student loyalty, keeping them engaged with the institution not only during their undergraduate studies but also in postgraduate studies.
In institutional practice, this becomes a four-step flow:
- Define the event you want to predict. Withdrawal, non-reenrollment and prolonged non-payment need different models.
- Gather enough history. Without several terms of labeled data, there is nothing to learn from.
- Choose the action trigger. A risk score only matters when an owner and a contact protocol are attached to it.
- Measure the effect of the intervention. Comparing groups that received and did not receive outreach separates a data project from a dashboard project.
Step four is the most neglected. Without it, the institution never knows whether the drop came from the action or from the calendar.
Dropout prediction is born in academic affairs, but the intervention runs through marketing, student services and finance, which is why student recruitment and retention works better as a single cycle than as two departments meeting at the end-of-term report.
Systematic monitoring of the data generated within the Educational Institution itself can reverse situations like these and help with educational management, the development of internal student retention programs, monitoring the performance of the academic community and in many other cases.
Even teaching performance can be monitored using Big Data, contributing to the development of continuing education programs for this audience.
How do you apply big data in 90 days without a data team?
By starting small, with one business question at a time and with data that already exists. A first cycle tends to deliver more when it produces one better decision than when it produces a complete architecture. The sequence below reflects field experience, not an official industry standard.
-
Days 1 to 30: inventory and a single question.
Map the datasets, their owners and their update frequency. Pick one question that has an owner and a budget attached, such as which channel brings students who enroll and stay through a second term.
-
Days 31 to 60: minimum integration and one dashboard.
Connect two or three sources, not all of them. Standardize identifiers, because without a reliable key to recognize the same person across systems nothing reconciles.
-
Days 61 to 90: first action and measurement.
Turn the dashboard into a decision routine: a prioritized queue for the admissions team, a list of students for preventive outreach or a reallocation of budget across channels. Document what changed and compare it with the prior period.
Choose a problem the institution already feels, because a painless project loses priority in the first busy month. And write down the definitions, since half the data arguments in higher education are really arguments about what "active student" means.
Returns tend to come faster when the dashboard connects to a broader plan for data science applied to student recruitment, with targets by program and by delivery mode.
What does privacy law require when you analyze student data?
Privacy law requires a defined legal basis for processing personal data and adherence to principles such as purpose limitation and data minimization. In operational language: the institution must know why it collects each field, disclose that to the individual and limit processing to what is necessary.
In the European Union, and for any institution handling data of people located there, the General Data Protection Regulation sets out those principles in Article 5 and lists the lawful bases for processing in Article 6. Consent is only one of several bases, and contract performance or legitimate interest often fit educational contexts better.
In the United States, the Family Educational Rights and Privacy Act governs education records. Once a student enrolls in a postsecondary institution, the rights of access, amendment and control over disclosure of personally identifiable information transfer to the student.
Brazil offers a useful third reference, since the Lei Geral de Proteção de Dados follows the GDPR structure closely.
The common failure is not the absence of a policy. It is the distance between the policy and the systems. An institution can publish an impeccable privacy notice and still email unprotected student spreadsheets between departments.
A mature project treats privacy as an architectural requirement: collecting less and better, recording the legal basis for each use, controlling access and setting retention periods.
Which mistakes stall big data projects in higher education?
The dominant mistake is starting with the tool. Data projects at educational institutions stall far more often for lack of a clear question, an owner and a decision routine than for lack of technology. A beautiful dashboard without an owner changes nothing.
The systematic review cited earlier documents recurring failure patterns: emphasis on algorithm performance over actual learning outcomes, weak statistical rigor in intervention studies and limited attention to ethics and privacy. Five versions of those patterns show up regularly in institutional practice.
-
Confusing reporting with deciding. If nobody acts after reading the number, the project is documentation, not management.
-
Ignoring base quality. Duplicate records and carelessly filled fields break any model. Bad data does not disappear, it just hides inside a chart.
-
Predicting without an intervention protocol. Knowing who will leave without defining who calls and with what offer only produces organized anxiety.
-
Treating AI as a shortcut around organized data. Gartner's finding on data foundations exists precisely because the reverse order does not work.
-
Leaving governance for last. Rebuilding collection and consent after the project is running costs far more.
There is also an expectation error. Analytics does not create demand where there is none. When the real problem is a program portfolio misaligned with the local market, data just shows the gap faster, and the fix returns to positioning work of the kind covered in practical ways to improve student enrollment.
How do micro-credentials relate to big data in higher education?
Micro-credentials are short certifications focused on one specific skill. The link to data is direct: demand analysis is what tells you which skill has traction, in which format and for which audience, and completion data is what shows whether the short pathway worked.
Three decisions depend on that reading. Which pathways to open, based on search behavior, enrollment history and interest surveys in your own base. How to price and package them, since a short cycle changes the acquisition cost math. And how to connect the short pathway to a degree or graduate program, using students you already serve.
Short-format offerings also tend to produce clean data faster, because the cycle closes in weeks rather than terms. That makes them a good laboratory for testing a decision routine before applying it to long programs.
Frequently asked questions about big data in higher education
So, is big data in higher education worth the investment?
It is, as long as the investment starts with organization rather than technology. With roughly a third of students at four-year institutions still not completing within six years, and nearly one in four not returning after the first year, deciding without data has become expensive.
What changed over the past decade is the starting point. The barrier used to be technical. Today it is organizational: who owns each dataset, which question the institution wants to answer first and who acts once the number is visible.
The good news is that the first cycle is modest. Two integrated sources, one question with an owner, a dashboard with few metrics and a decision routine already change the budget conversation within a term.
If your institution is at that point, with scattered data and a desire to move past intuition, the next step is to design the initial scope alongside people who have done it before. You can talk to a mkt4edu specialist to review your current setup.








 Portugal