

Few files cause as much confusion as the sitemap. It is treated either as a bureaucratic formality someone configured once, or as a magic lever capable of fixing a traffic drop.
Neither reading helps. Knowing how to create a sitemap and, above all, how to maintain it is a quiet maintenance task, with its effect concentrated on one specific stage of search.
This article covers that stage, the technical limits of the file and the errors that make a well-intentioned sitemap get in the way instead of helping.
What is a sitemap and which problem does it solve?
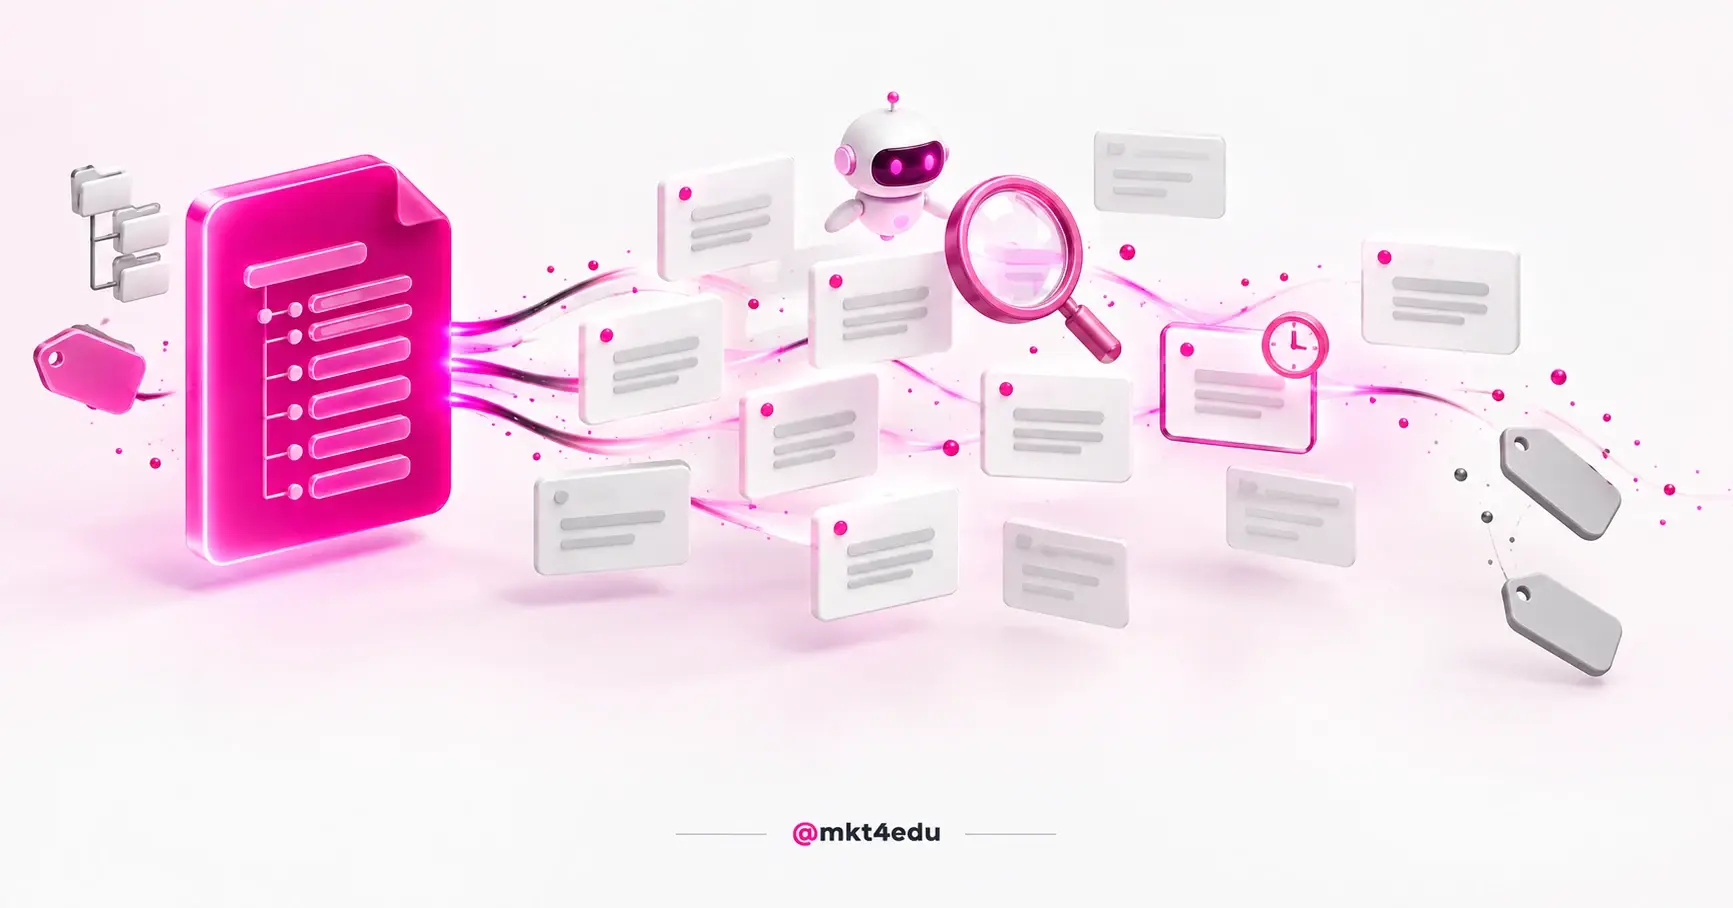
A sitemap is a file that tells search engines which pages, videos and other files exist on the site. It solves a specific problem, which is URL discovery, by handing over the ready-made list instead of letting the crawler find each page by following links.
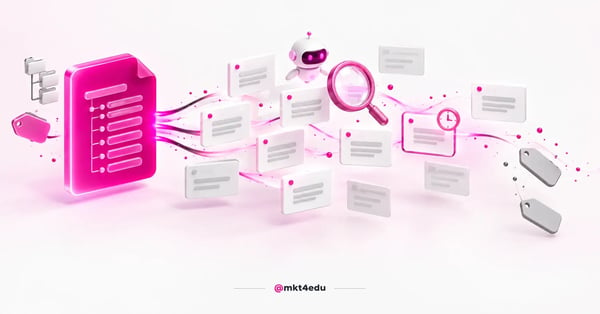 Caption: the sitemap hands the ready-made list of URLs to the crawler instead of waiting for it to find each page through a link
The scope is bounded: the file helps search engines discover URLs (Uniform Resource Locator, the address of each page), but does not guarantee that every item listed will be crawled and indexed.
That sentence separates what the sitemap does from what it does not. Discovery is different from indexing, and indexing is different from position.
There is also the case where the file is dispensable. A small site, with around five hundred pages or fewer and comprehensive internal linking between them, tends to be discovered without it.
Catalogue sites rarely fit that description. Adding up program or product pages, campuses, blog, forms and downloadable resources, the volume passes that number comfortably.
There are two further scenarios where the file weighs more: a new site with few external links pointing to it, and a site with a lot of video or image content. Institutions are usually in both at once after a redesign.
How to create an XML sitemap: formats and limits
Creating an XML sitemap means generating a file in that markup language with the list of the site's URLs. Google accepts other formats, such as RSS, Atom and plain text, but describes XML as the most versatile of the sitemap formats.
The limits are fixed and apply to every format. A single file cannot exceed 50 MB uncompressed or 50,000 URLs.
When the site exceeds either of those limits, the guidance is to split it into several files and create a sitemap index, a single file pointing to the others.
The simplest sitemap example has only the URL and the last modification date per page, repeated item by item. In plain text format, each line carries one URL and nothing else, which works well for large, repetitive lists.
In practice, almost no site writes that file manually. Generation is automatic in the platform, and the useful effort sits in curating what goes in.
The curation rule fits in one sentence: the sitemap lists the pages you want to see in search. A redirecting URL, a page marked not to be indexed and a duplicate version of a piece of content should not be there.
Video: the technical checklist the sitemap review fits into, on the mkt4edu channel (video in Portuguese)
Which sitemap tags does Google use and which does it ignore?
Google ignores priority and change frequency values, and uses the last modification date when it is consistent and verifiably accurate. That settles at once two discussions that still consume time in team meetings.
The priority tag was conceived to signal the relative importance of each page. It does not work, because the search engine does not accept an importance ranking declared by the site itself.
The change frequency tag had the same logic and the same fate. Declaring that a page changes daily does not make the crawler come back more often.
The last modification date is the exception, and the condition is worth understanding. Google uses that value when it is reliable, and the condition is that it reflects the date of the page's last significant change.
Hence the most common error with that tag, which is updating the date in bulk without anything having actually changed. When the signal turns out to be false, it stops being taken into account.
See how the three tags behave:
|
Tag |
Does Google use it? |
What to do |
|
lastmod (last modification) |
Yes, if accurate |
Keep it faithful to the page's real change |
|
changefreq (frequency) |
No |
Do not spend configuration time on it |
|
priority |
No |
Do not use it as a ranking lever |
Table: Google's stated behaviour for the three optional tags of the sitemap protocol
The practical conclusion is comfortable. A useful sitemap is a clean list of URLs with honest dates, and any effort beyond that pays off little.
How do you create a sitemap in WordPress and HubSpot?
Both platforms generate the file automatically, so creating a sitemap in WordPress or HubSpot is less a creation task and more a checking task. What differs between them is the degree of control over which page types enter the list.
In WordPress, the system has published a native sitemap since version 5.5, and SEO plugins usually replace it with a version offering more options. The point of attention is that both can coexist, and the site then serves two competing files.
Checking in WordPress starts with knowing which file is actually active. After that, the work is excluding from the list the content types that should not appear in search, such as archive pages and empty taxonomies.
In HubSpot, the sitemap is generated by the content management system itself and reflects the pages and blogs published on the domain. Control happens page by page, through each piece of content's indexing setting.
Teams migrating between platforms have an extra precaution, because that is when the file drifts furthest from reality. The walkthrough for migrating a blog from WordPress to HubSpot details which URLs change and need reviewing in the sitemap.
In both cases the golden rule is the same. If a page is marked not to be indexed and still appears in the sitemap, the site is giving two opposite instructions at the same time.
How do you build a good sitemap structure on a large site?
A good sitemap structure splits the file by content type and gathers everything in an index. Instead of a single list with tens of thousands of URLs, the site has one file for programs, another for the blog, another for institutional pages, and an index pointing to all three.
The gain from that split is not technical, it is diagnostic. With separate files, the Search Console report shows how many pages were discovered in each group, and a concentrated problem becomes visible immediately.
A blog's sitemap structure is usually the simplest, because the content is homogeneous and the publication date organises everything. The challenge appears in program pages, which change name, delivery mode and URL every cycle.
For institutions with many campuses, splitting by region or campus as well tends to pay off. When an entire unit disappears from search, the drop shows up in a single file instead of diluted in the total.
That grouping logic speaks to the way editorial content itself is organised, and the topic cluster reasoning helps decide which sets of pages make sense to treat together.
A note on expectations is worth adding. Reorganising the sitemap improves discovery and diagnosis, but does not reposition pages, because the stage it serves comes long before ranking.
How do you submit the sitemap and track what Google read?
Submission happens through the Sitemaps report in Google Search Console, which also keeps the submission history and flags processing errors. There are two documented alternatives: the Search Console application programming interface and listing the file in robots.txt, with no manual submission.
After submission, the report shows one of three statuses, and each calls for a different action. Success means the file was fetched and read without errors. Couldn't fetch means Google could not access the file. Has errors means it was read but has problems.
The most informative column in the report is discovered pages. Comparing that number with how many URLs you know exist reveals, in seconds, whether the file is complete.
A large gap between discovered and existing is rarely a Google failure. In general it is a page missing from the file, or a file left outdated after a structural change.
Tracking that report belongs to the same verification routine as the other panels, described in the material on how Google Search Console works.
When the report shows couldn't fetch, the problem is usually before the file. It is worth confirming that crawler access is open, following the validation of Googlebot crawling on the server and on the delivery network.
Which sitemap errors appear most on catalogue sites?
The most frequent sitemap errors do not break anything visibly, and that is exactly why they last for years without anyone noticing. They produce friction in discovery, consume crawling on useless URLs and distort the diagnosis, without ever raising a clear alert in Search Console.
On sites with an extensive catalogue, five patterns repeat:
- Pages for closed admissions cycles stay listed, even after being redirected or removed.
- The file keeps old program URLs after a site redesign, pointing to chained redirects.
- Form thank-you pages enter the file and compete for crawling with program pages.
- The last modification date is rewritten in bulk by a platform routine, with no real content change.
- Nobody is responsible for the file, so it is only reviewed once traffic has already dropped.
The last item sustains the previous four. A sitemap with no owner becomes a historical record of the site that used to exist, not a map of the site that does.
A quarterly checking routine solves most of it. Opening the file, comparing it with the list of active pages and checking the discovery number in the report takes less than an hour on a mid-sized site.
That precaution is neighbour to another one that usually comes up in the same conversation, the llms.txt file proposed to guide language models. The difference is that the sitemap has confirmed use by Google, and the other does not.
What does the sitemap change in AI search?
The sitemap acts on discovery, and discovery is the first step to appearing anywhere, including in AI (Artificial Intelligence) generated answers. Google's generative features work on the same index as traditional search, so a page that was not discovered is not a citable page.
That puts the file in a modest and necessary position. It does not improve content quality nor increase the chance of citation on its own merit, but without it part of the site may never reach the stage where merit is assessed.
The temptation, with the arrival of generative AI, was to look for a new file that would play that role for the models. So far, Google has confirmed use of the sitemap and has not confirmed use of alternative formats proposed by the market.
For the content team, the practical reading is simple. The levers for citation remain the same ones as well-executed SEO (Search Engine Optimization), and the sitemap is silent infrastructure underneath them.
The separation between what is the technical layer and what is the content layer in that contest is detailed in the comparison between SEO, AEO and GEO.
There is also a third layer, which starts after the click. SXO (Search Experience Optimization) deals with the experience the visitor finds on arrival, and no discovery file interferes with it.
Video: what influences AI citation once discovery through the sitemap is settled, on the mkt4edu channel (video in Portuguese)
Frequently asked questions about how to create a sitemap
Where do you start fixing your site's sitemap?
Start by opening the file that is live today, before any discussion about the ideal structure. It is worth confirming three things: which sitemap the site actually serves, how many URLs it lists and how many pages Search Console says it discovered from it.
That comparison settles the diagnosis in the first hour of work. A list smaller than the site means incomplete coverage. A larger list means dead URLs taking up space.
After that, the priority is splitting the file by content type and defining who is responsible for it. Without an owner, any structure drifts from reality again in the next cycle of changes.
If your site went through a recent redesign, a platform change or a catalogue reorganisation, there is a good chance the sitemap describes a site that no longer exists. It applies to a program catalogue, a product line or a services portfolio, because the symptom is the same.
Talk to our team to review the domain's technical structure and align the sitemap with what is actually published.







 Portugal